
Zongyang Qiu
he/him
An MPhil student at HKUST(GZ). B.S. in Computer Science from Fudan University.
Seek, and you will find. (Matthew 7:7)
Posts by Collection
portfolio
Portfolio item number 2
This is an item in your portfolio. It can be have images or nice text. If you name the file .md, it will be parsed as markdown. If you name the file .html, it will be parsed as HTML.
publications
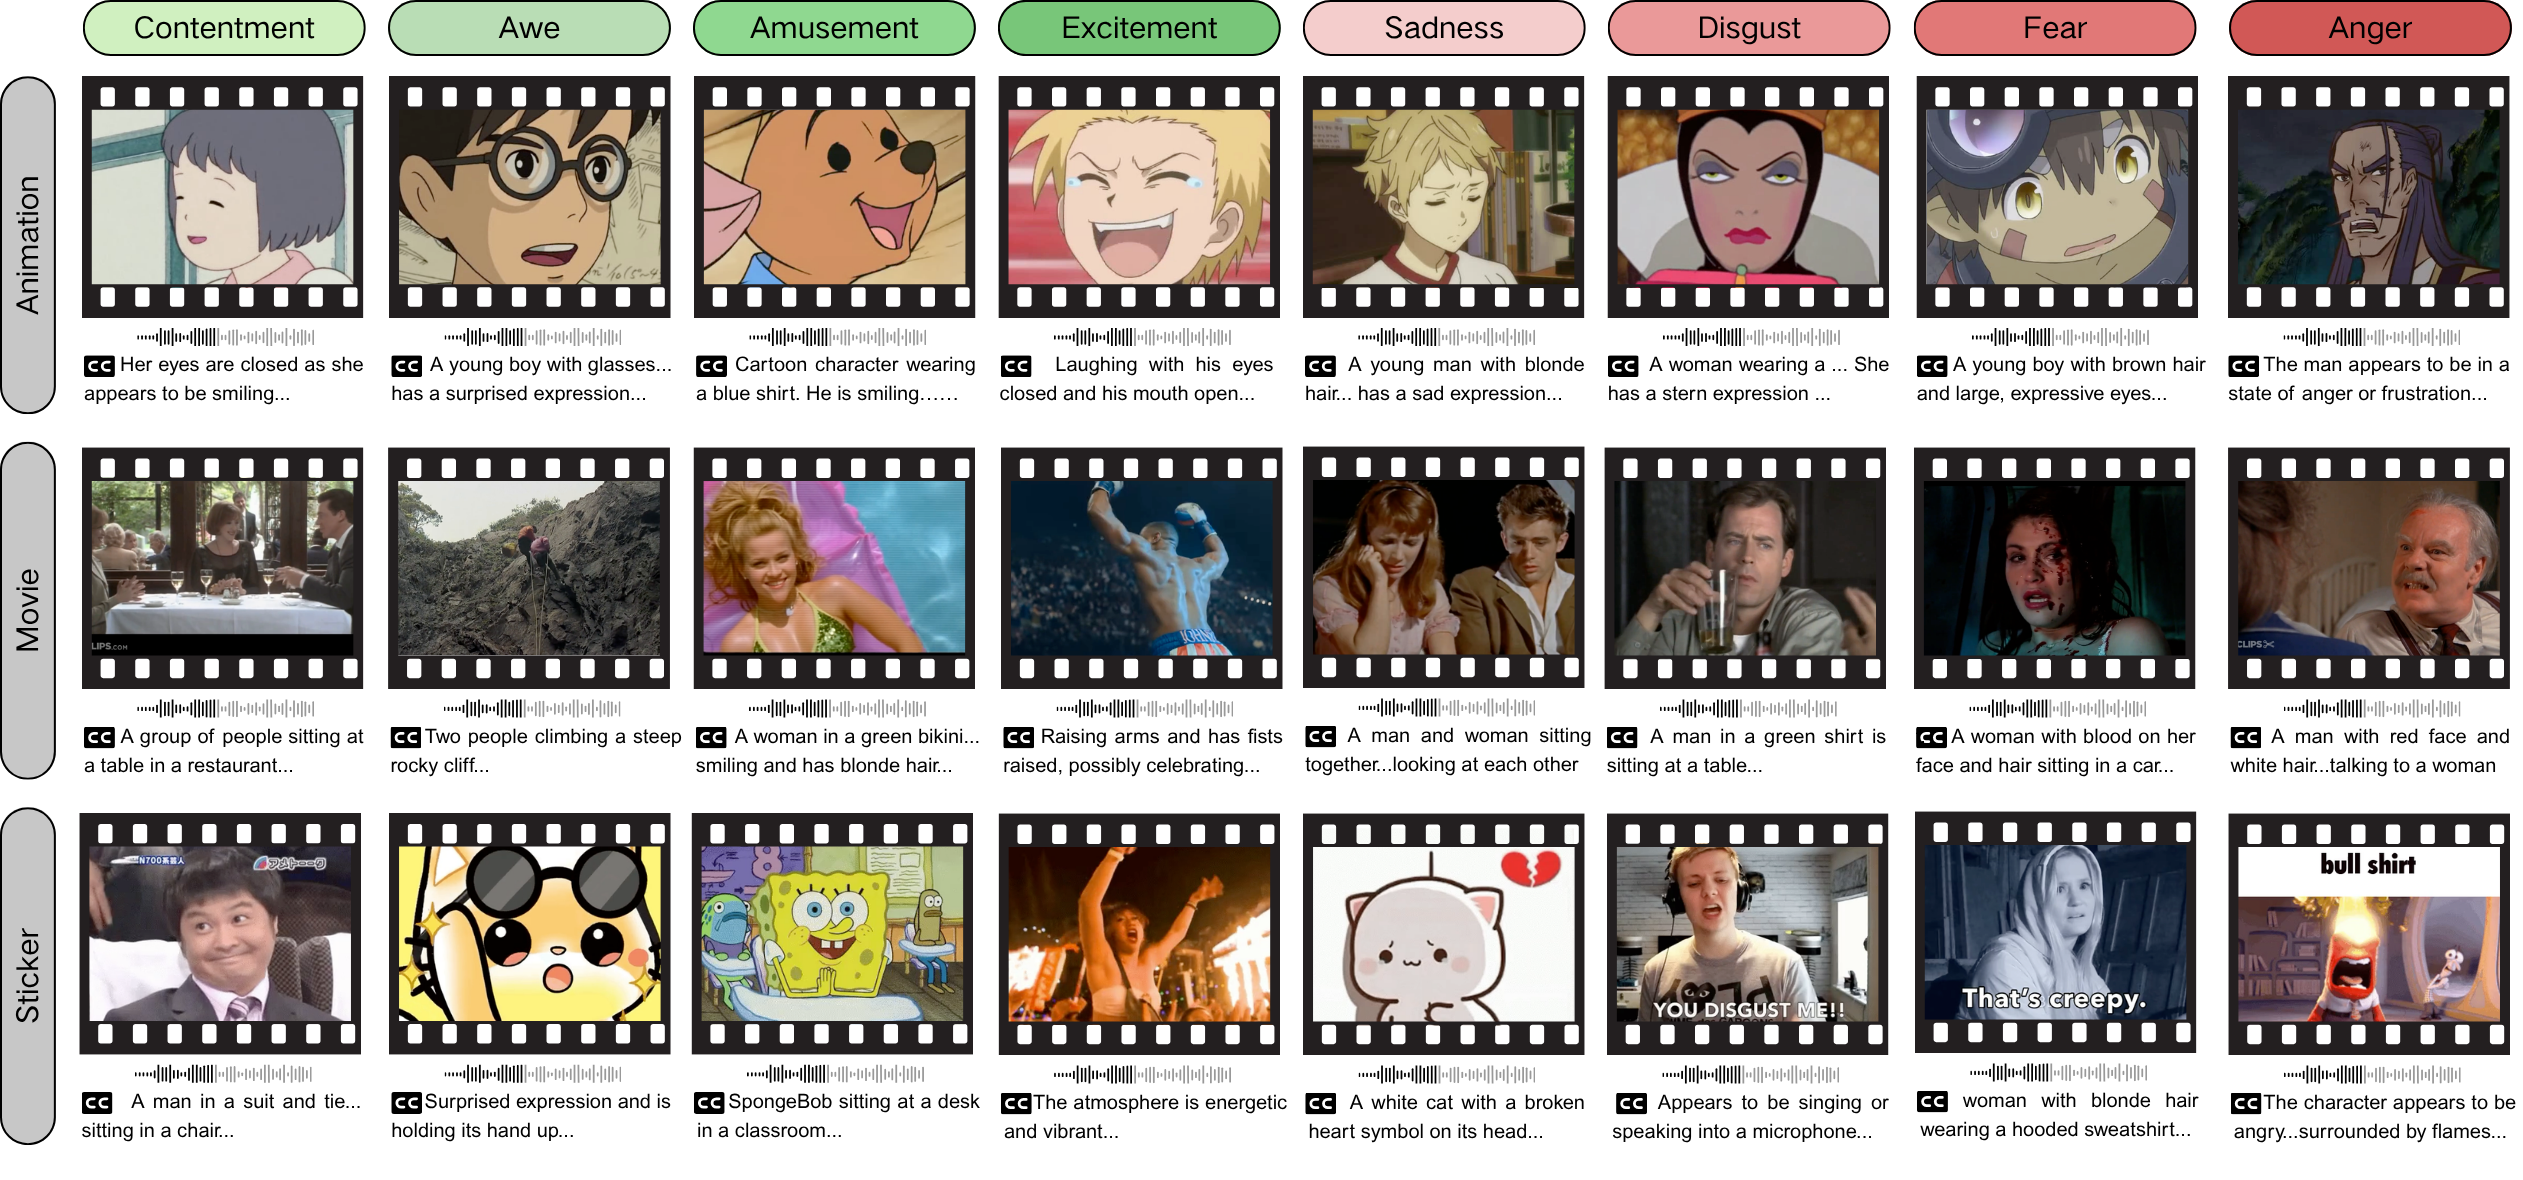
EmoVid: A Multimodal Emotion Video Dataset for Emotion-Centric Video Understanding and Generation
Zongyang Qiu*, Bingyuan Wang*, Xingbei Chen, Yingqing He, Zeyu Wang
AAAI 2026 (Oral)
Abstract: Emotion plays a pivotal role in video-based expression, but existing video generation systems predominantly focus on low-level visual metrics while neglecting affective dimensions. Although emotion analysis has made progress in the visual domain, the video community lacks dedicated resources to bridge emotion understanding with generative tasks, particularly for stylized and non-realistic contexts. To address this gap, we introduce EmoVid, the first multimodal, emotion-annotated video dataset specifically designed for creative media, which includes cartoon animations, movie clips, and animated stickers. Each video is annotated with emotion labels, visual attributes (brightness, colorfulness, hue), and text captions. Through systematic analysis, we uncover spatial and temporal patterns linking visual features to emotional perceptions across diverse video forms. Building on these insights, we develop an emotion-conditioned video generation technique by fine-tuning the Wan2.1 model. The results show a significant improvement in both quantitative metrics and the visual quality of generated videos for text-to-video and image-to-video tasks. EmoVid establishes a new benchmark for affective video computing. Our work not only offers valuable insights into visual emotion analysis in artistically styled videos, but also provides practical methods for enhancing emotional expression in video generation.
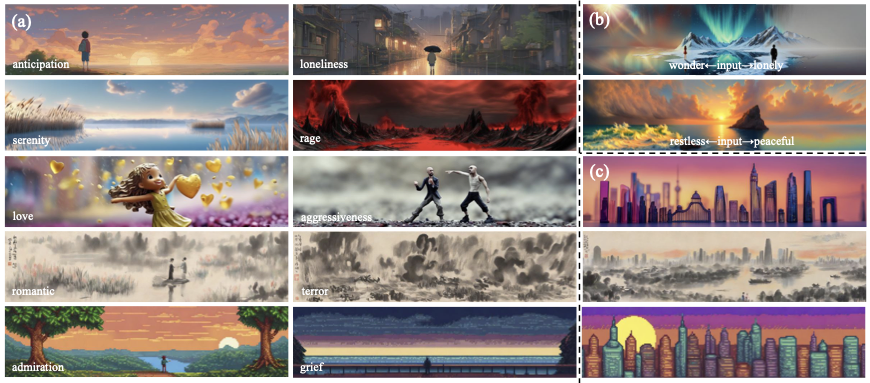
EmoSpace: Fine-Grained Emotion Prototype Learning for Immersive Affective Content Generation
Bingyuan Wang, Xingbei Chen, Zongyang Qiu, Linping Yuan, Zeyu Wang
arXiv preprint
Abstract: Emotion is important for creating compelling virtual reality (VR) content. Although some generative methods have been applied to lower the barrier to creating emotionally rich content, they fail to capture the nuanced emotional semantics and the fine-grained control essential for immersive experiences. To address these limitations, we introduce EmoSpace, a novel framework for emotion-aware content generation that learns dynamic, interpretable emotion prototypes through vision-language alignment. We employ a hierarchical emotion representation with rich learnable prototypes that evolve during training, enabling fine-grained emotional control without requiring explicit emotion labels. We develop a controllable generation pipeline featuring multi-prototype guidance, temporal blending, and attention reweighting that supports diverse applications, including emotional image outpainting, stylized generation, and emotional panorama generation for VR environments. Our experiments demonstrate the superior performance of EmoSpace over existing methods in both qualitative and quantitative evaluations. Additionally, we present a comprehensive user study investigating how VR environments affect emotional perception compared to desktop settings. Our work facilitates immersive visual content generation with fine-grained emotion control and supports applications like therapy, education, storytelling, artistic creation, and cultural preservation. Code and models will be made publicly available.
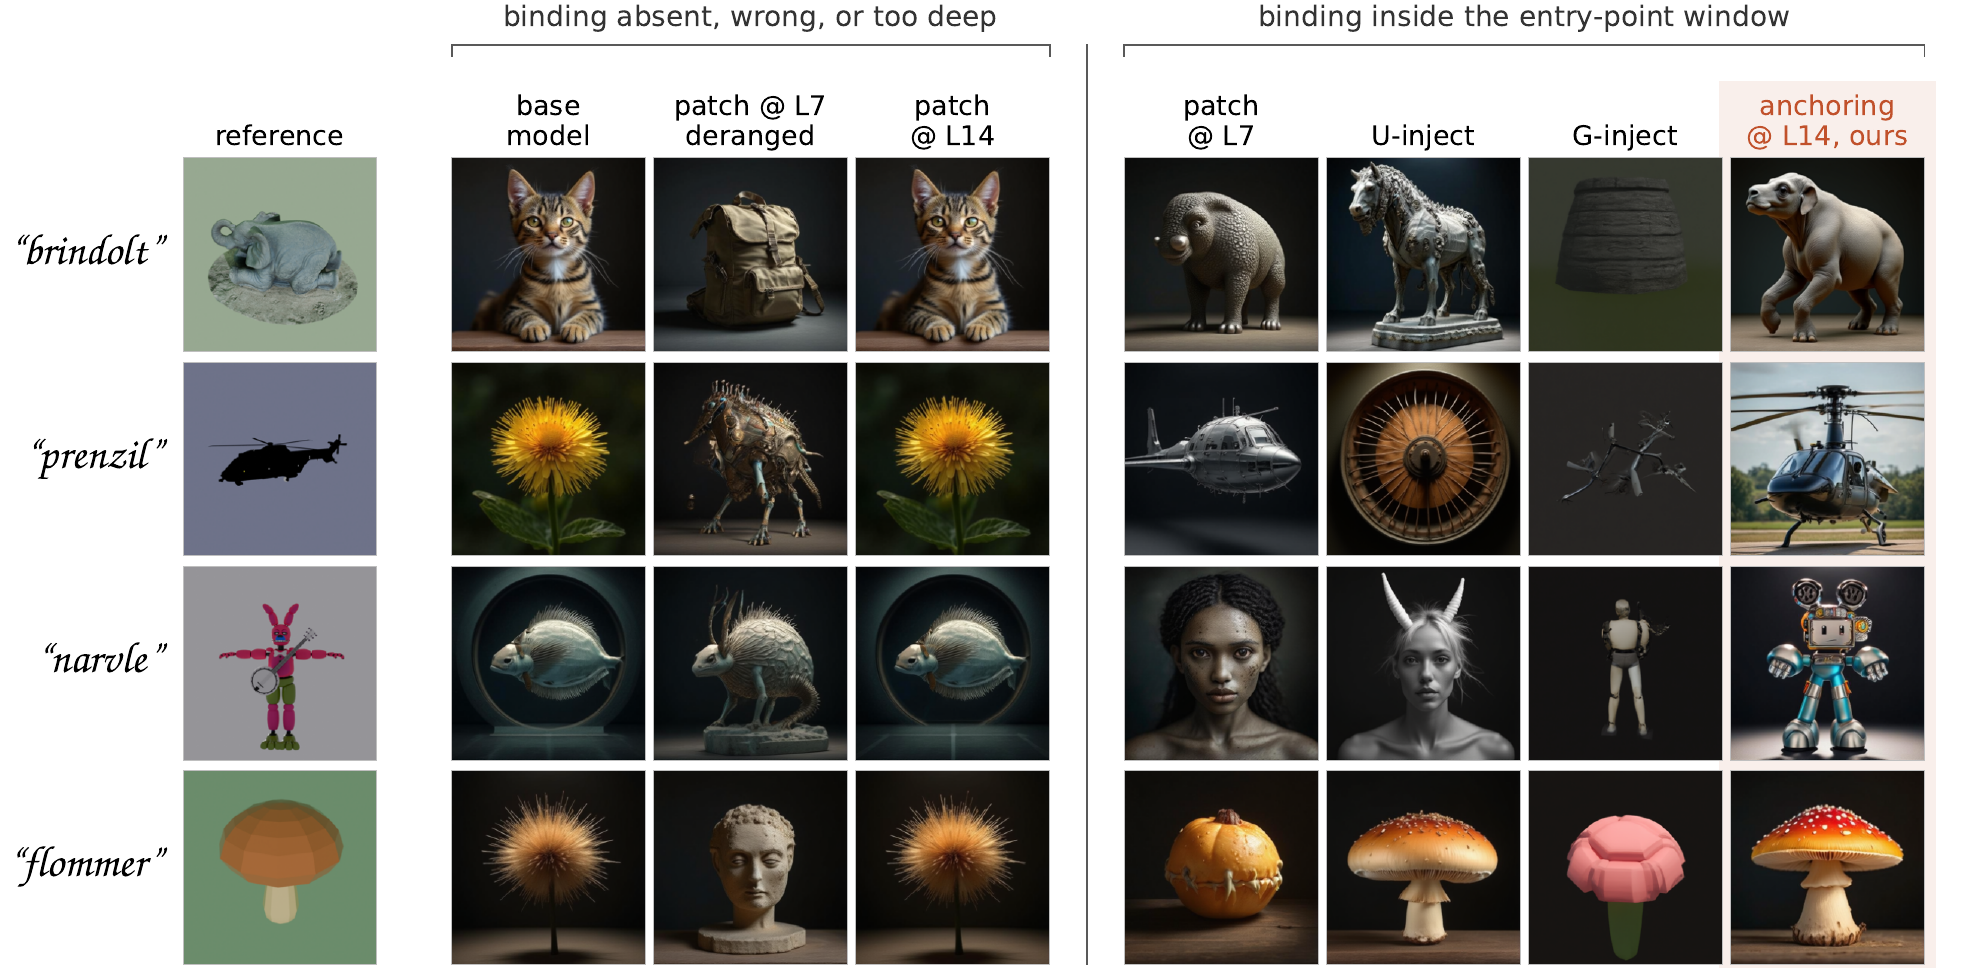
Where a New Concept Must Enter: Entry Point Gates Cross-Task Usability in Unified Multimodal Models
Zongyang Qiu, Yihan Wu, Kaixuan Fan, Bo Li, Hui Xiong
arXiv preprint
Abstract: Unified multimodal models (UMMs) are motivated by the hope that understanding and generation reinforce each other but controlled ablations repeatedly find that adding a generation objective leaves understanding flat. Joint-training studies cannot settle the disagreement: with overlapping supervision, a gain cannot be attributed to the architecture rather than the data. To further investigate the relationship between the two directions in UMMs, we separate them by construction. A novel visual entity, a rendered 3D asset paired with a pseudo-word screened for absence from the frozen model’s behavior, is bound through exactly one task direction, and the untrained direction is then measured. We find that the channel is real in both directions, but the directions differ in kind: generation training installs a name the model can only match among candidates; understanding training installs one it can also produce. What governs cross-task usability is where the binding enters the shared computation. An alignment probe predicts export across 36 configurations (Spearman ρ = +0.68). That objective’s alignment term, maximized in closed form over activations with every weight frozen, makes a concept drawable when injected at layer 7 of 28 and is indistinguishable from the base model from layer 14 on, while the weight-based version of the same edit peaks at layers 10-14. In an observational series of four models, this window appears only where the understanding pathway is a semantic vision encoder, suggesting that unified weights are not enough: the two directions must share a semantic format at the entry point. Exploiting the rule, a mid-stack alignment objective acquires the concept for a 0.1% relative loss of the model’s general text-to-image ability, against 41% for the standard generative route.
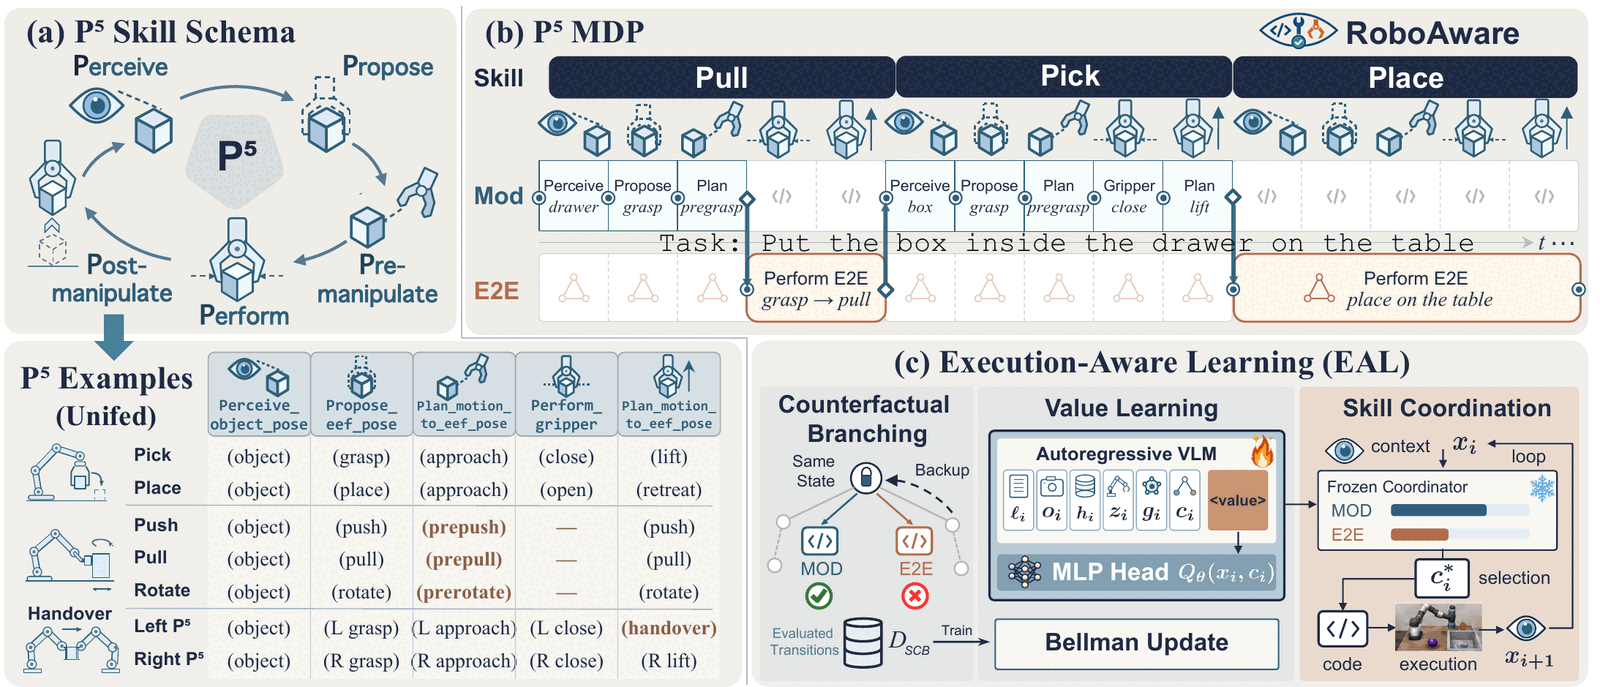
RoboAware: Learning to Coordinate Embodied Skills from Counterfactual Outcomes
Bohan Zhou*, Xingbei Chen*, Emily Huang, Weilin Ruan, Haojian Huang, Yehang Zhang, Zexi Li, Wenqian Li, Qize Yu, Zetian Song, Leyi Wu, Jinghao Li, Mingxuan Song, Xinrun Xu, Zongyang Qiu, Yangkai Wei, Tianyi Zhang, Kaiwen Zhou, Yinchuan Li, James Cheng
arXiv preprint
Abstract: Embodied coding agents can combine modular robot skills with frozen end-to-end policies, yet effective composition requires anticipating which policy family will succeed in the current physical state. We present RoboAware, which builds on coding agents’ skill orchestration by learning only a state-conditioned responsibility coordinator from counterfactual outcomes. Inspired by the success of REPL, we propose the P5 schema and formulate a hierarchical MDP based on it. P5 organizes skills uniformly into five semantic stages, defining where responsibility can be compared. To address the lack of counterfactual branch outcomes in existing work, we introduce State-Locked Counterfactual Branching (SCB), which restores the same training state to generate and execute a code block from each admissible family, exposing outcomes that selected-branch experience leaves unobserved. Building on this, we propose Execution-Aware Learning (EAL), which combines Monte Carlo tree search with Q-learning to distill these outcomes into family-conditioned values. At deployment, the coordinator selects the policy family according to observable context, and the frozen coding agent generates the next local code block. Comprehensive single-episode evaluations on 100 tasks show that RoboAware reaches a 77.0% overall success rate, with SOTA averages of 90.0% on RoboSuite, 73.8% on diverse LIBERO-Pro task clusters, and 90.0% on challenging RoboTwin bimanual tasks, outperforming existing code-as-policy and VLA-harness baselines.
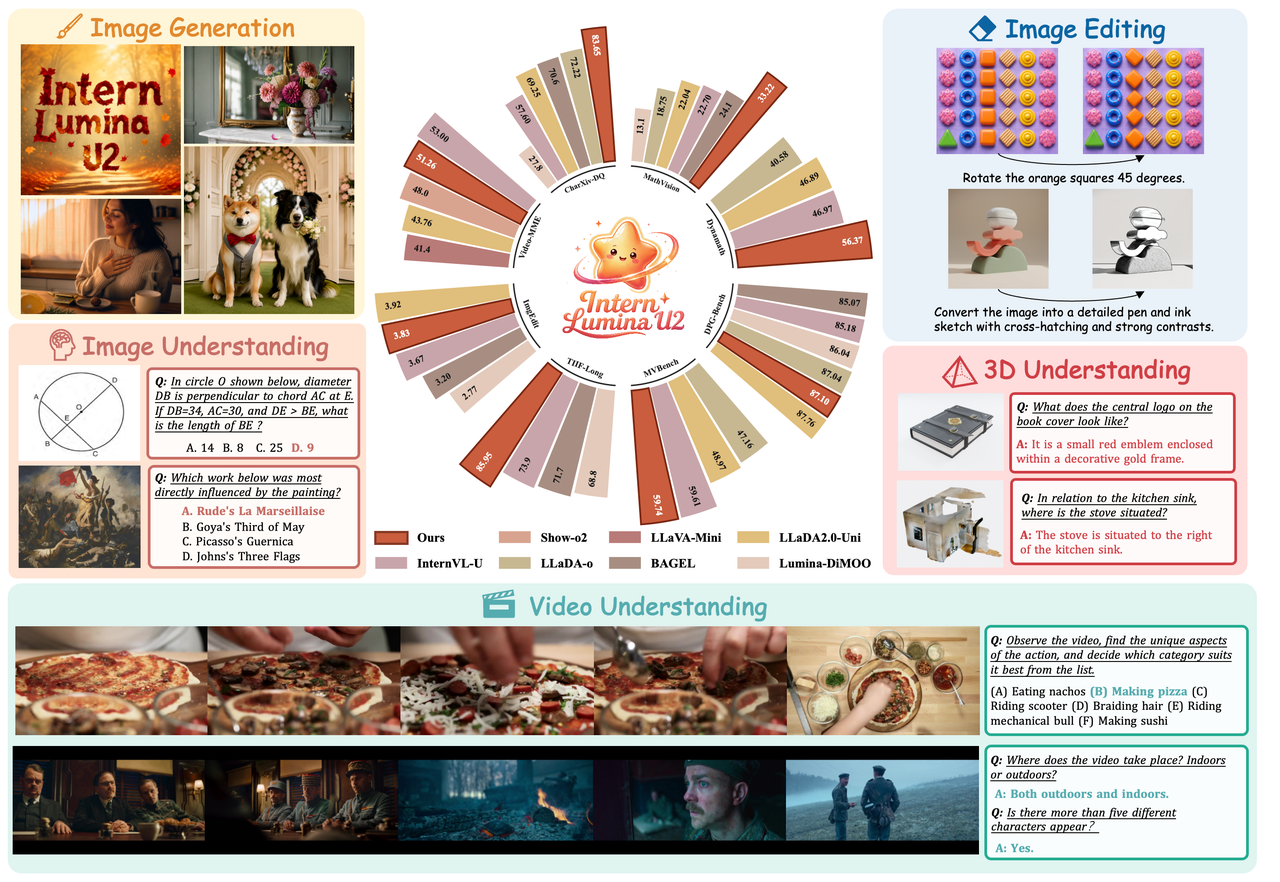
Intern Lumina U2: A Multi-Codebook Diffusion Large Language Model for Omni-Visual Understanding and Image Generation
Qian Yu*, Zongyang Qiu*, Juncheng Yan*, Hongliang Li*, Qi Qin*, Keqi Wang*, Siqi Luo, Junkui Ju, Yapeng Mi, Tiantian Lu, Tian Liu, Pengyu Xie, Chenhao Ji, Minghui Zhang, Yiang Zhao, Siyu Yan, Haiying Xu, Yanbo Wang, Jianghan Shen, Yuandong Pu, Jiayi Lei, Borui Zhang, Jinxin Shi, Bo Zhang, Yuhang Zang, Shenglong Ye, Lixin Gu, Hongjie Zhang, Linghan Liu, Xinyuan Chen, Yuewen Cao, Lihe Zhang, Xiaohong Liu, Junjun He, Qiangwei Liu, Qi Zhang, Yu Cheng, Tianfan Xue, Hui Xiong, Chang Xu, Yu Qiao, Yihao Liu, Bin Fu
arXiv preprint
Abstract: Unified multimodal generation covers discrete, continuous, and hybrid paradigms. Discrete approaches with single-codebook visual tokenizers align naturally with text modeling but have limited representational capacity. Continuous and hybrid approaches retain richer visual representations, but they model text and images in heterogeneous spaces with different training objectives, potentially introducing optimization conflicts between modalities with misaligned representation spaces. These choices expose a central question: how to efficiently model high-capacity visual representations alongside textual content in a shared optimization space within a single backbone. We present Intern Lumina U2, to our knowledge the first diffusion language model to represent multi-codebook visual tokens in a fully discrete space. Each visual position is represented by a group of codes from complementary codebooks, increasing its representational capacity while preserving compatibility with discrete text modeling. At the input, the embeddings are concatenated at each position; at the output, a lightweight multi-codebook autoregressive head predicts the codes within each position sequentially, while the diffusion backbone processes all positions in parallel. Built on the unified 4D representation of AToken, Intern Lumina U2 supports image, video, and 3D inputs within a single backbone and achieves leading performance among unified models in visual understanding, image generation, and image editing. We further build a full-stack training, inference, and evaluation system on both Ascend and NVIDIA platforms to verify the cross-platform effectiveness of our model. We also improve the inference efficiency through a stability-aware sampling strategy, which combines confidence-plateau-guided unmasking approach with drift-triggered cache refreshing mechanisms, accelerating image generation by 4.45×.
talks
Talk 1 on Relevant Topic in Your Field
UC San Francisco, Department of Testing
This is a description of your talk, which is a markdown file that can be all markdown-ified like any other post. Yay markdown!
Tutorial 1 on Relevant Topic in Your Field
UC-Berkeley Institute for Testing Science
This is a description of your tutorial, note the different field in type. This is a markdown files that can be all markdown-ified like any other post. Yay markdown!
Talk 2 on Relevant Topic in Your Field
London School of Testing
This is a description of your talk, which is a markdown files that can be all markdown-ified like any other post. Yay markdown!
Conference Proceeding talk 3 on Relevant Topic in Your Field
Testing Institute of America 2014 Annual Conference
This is a description of your conference proceedings talk, note the different field in type. You can put anything in this field.
teaching
Teaching experience 1
University 1, Department
This is a description of a teaching experience. You can use markdown like any other post.
Heading 1
Heading 2
Heading 3
Teaching experience 2
University 1, Department
This is a description of a teaching experience. You can use markdown like any other post.